Customers and service teams
People seeking factual explanations of policy wording, with page citations they can inspect.
02 · RAG · LLM evaluation
I built a policy-question assistant that finds supporting clauses, cites its sources and shows why it answers or refuses.
Problem
A simple insurance question can depend on definitions, exclusions and conditions several pages apart. I built QuoteGuard to retrieve those passages, answer with page references and refuse requests for advice or pricing. I tested retrieval and refusals separately so I could check each part of the system.
People seeking factual explanations of policy wording, with page citations they can inspect.
The assistant explains the supplied document but does not recommend cover, personalise advice or generate a premium.
If retrieval finds no support, the assistant should say it cannot answer from the document.
Data
The source is an Allianz Business Insurance product disclosure statement. A structure-preserving parser recovered 619 sections and their page locations. Evaluation material is kept separate from the document chunks used by the retriever.
Approach
I combined two text-search methods, then reranked the candidate passages before producing a cited answer. Each response includes a trace showing which checks passed or caused a refusal: pricing, advice, prompt injection, document scope or supporting evidence.
Implementation scope: the professional implementation listed in my résumé used Azure OpenAI and Azure AI Search, with RAGAS evaluation work and MLflow experiment tracking. The public repository is intentionally portable: it uses TF-IDF/BM25 hybrid retrieval, a cross-encoder reranker, local or API language-model clients and an extractive fallback. The metrics on this page come from the versioned public evaluation artefacts unless stated otherwise.
The linked repository contains the portable pipeline, evaluation code and saved results. The professional Azure implementation is separate and is not included.
System architecture
The browser demo uses BM25 search, rule-based checks and quoted passages. It omits the language model, cross-encoder and learned injection detector; all processing stays in your browser.
Evaluation method
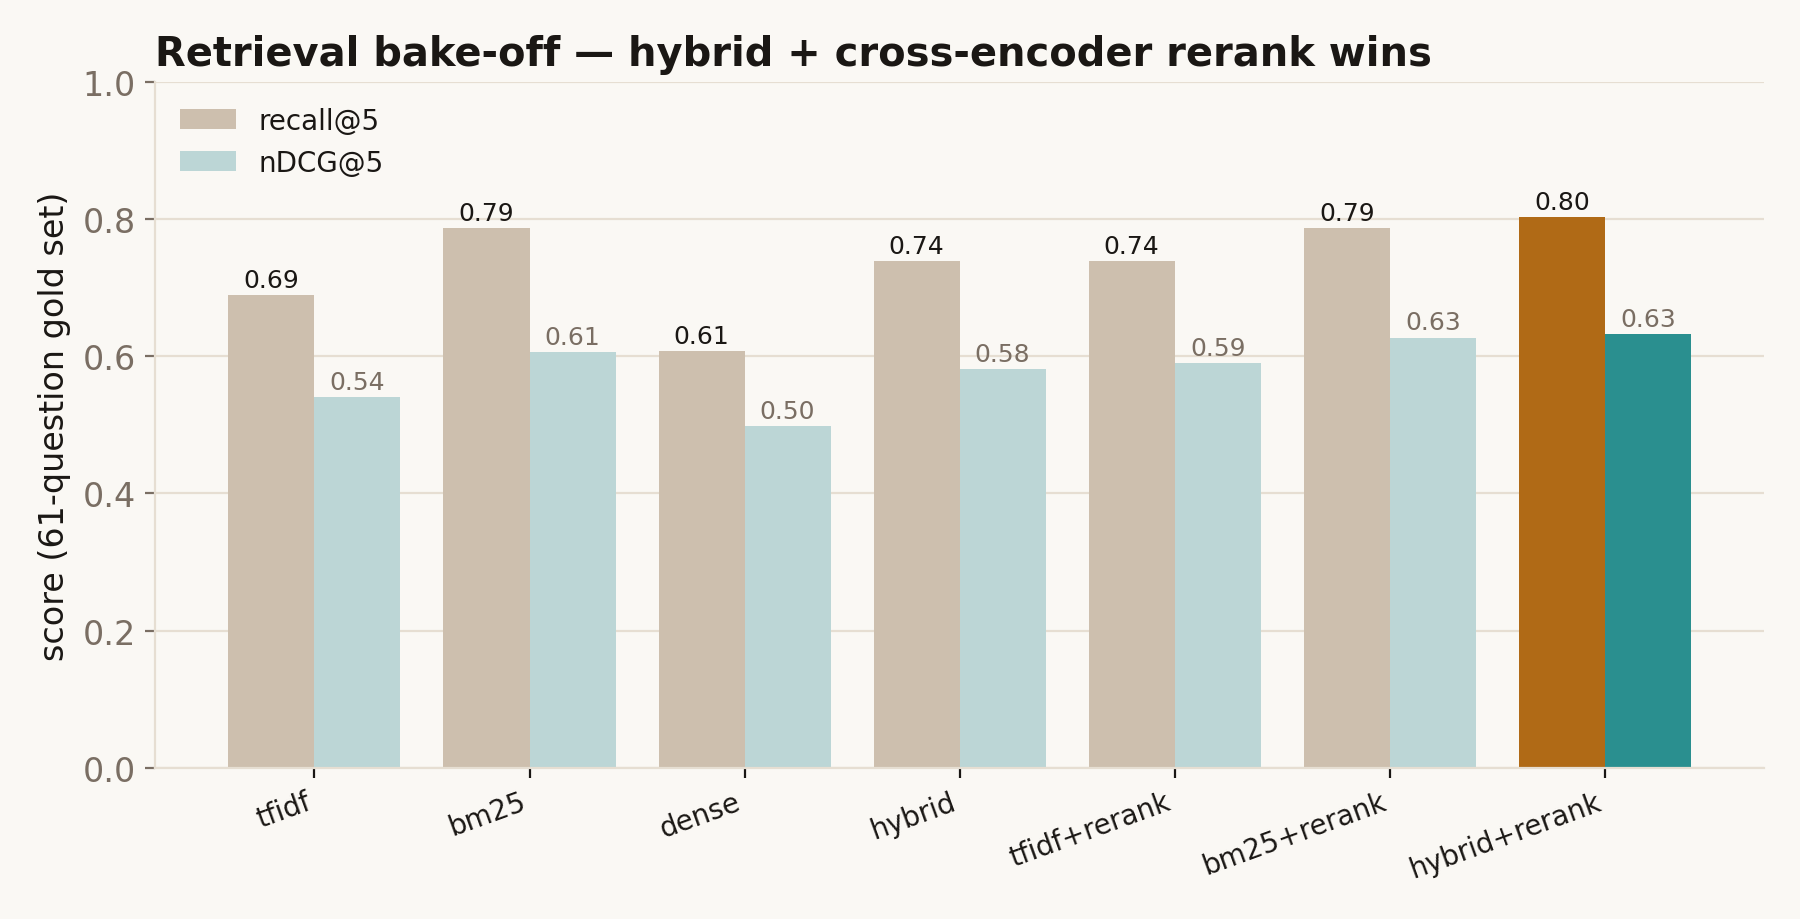
Retrieval evaluation: the 61 answerable questions are run through each retrieval configuration. A hit is defined by overlap with the gold supporting page. Recall@5 asks whether the answer page appears anywhere in the top five; hit@1, MRR@5 and nDCG@5 capture rank quality. Bootstrap confidence intervals are retained in the project artefacts.
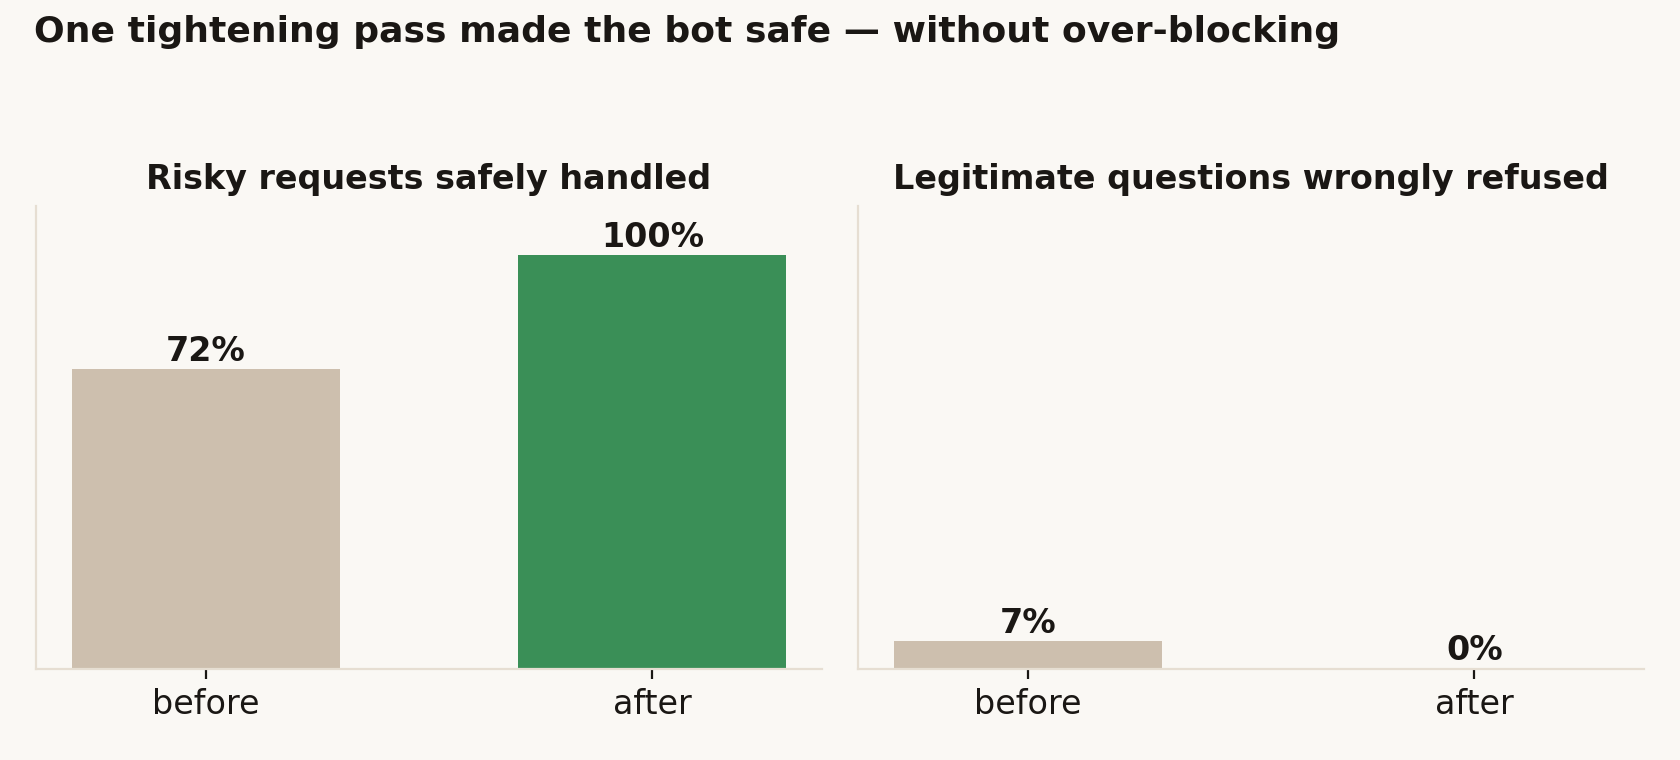
Guardrail evaluation: 40 adversarial prompts and 30 benign controls are scored deterministically. Safe-rate measures correct handling of risky prompts; benign false-positive rate catches a system that becomes “safe” by refusing useful questions.
Answer evaluation: outputs record whether a cited page was actually retrieved and preserve the evidence shown to the answerer. In the Azure work, RAGAS experiments and MLflow runs were used to compare broader response-quality dimensions; those scores are not presented here because they are not in the public repository artefacts.
Results
| Retriever | Hit@1 | Recall@5 | MRR@5 | nDCG@5 |
|---|---|---|---|---|
| TF-IDF | 0.410 | 0.689 | 0.509 | 0.540 |
| Dense (bge-small) | 0.377 | 0.607 | 0.466 | 0.498 |
| TF-IDF + rerank | 0.475 | 0.738 | 0.566 | 0.590 |
| Hybrid + rerank | 0.492 | 0.803 | 0.596 | 0.632 |
Failure cases & trade-offs
TF-IDF looked strongest on an early 20-question set. On 61 answerable questions, BM25 clearly beat it. The earlier result had been overfit to a narrow sample.
Dense embeddings were weakest on this term-heavy policy. That does not imply dense retrieval is generally worse; it means the corpus and questions rewarded exact terminology.
The 100% safe-rate is on 40 prompts used during one tighten-and-rerun cycle. It is evidence that the identified gaps were closed, not proof against unseen attacks.
Recall@5 shows that supporting pages were surfaced. It does not by itself prove that every generated answer was complete, faithful or appropriately qualified.
Layout, terminology and policy structure vary by insurer and product. Parser and retrieval choices need retesting across a broader document set.
What I would improve next
Live demo & source
This lightweight demo runs entirely in your browser. It loads the public policy chunks only when opened, uses BM25 retrieval and shows its guardrail trace and cited evidence. No question is sent to an API.
Faithful but lighter: this browser version omits LLM synthesis, the cross-encoder reranker and the learned injection model. It demonstrates retrieval, heuristic guardrails, extractive grounding and citation checks.
Open this panel to load the in-browser engine.